2026年10月13日
Gemini 4 Argon 标志着在物理理解、代码生成和视觉语义推理方面的阶跃式变化——解锁机器人技术栈中的新工作流,并加速迈向物理AGI的进程。
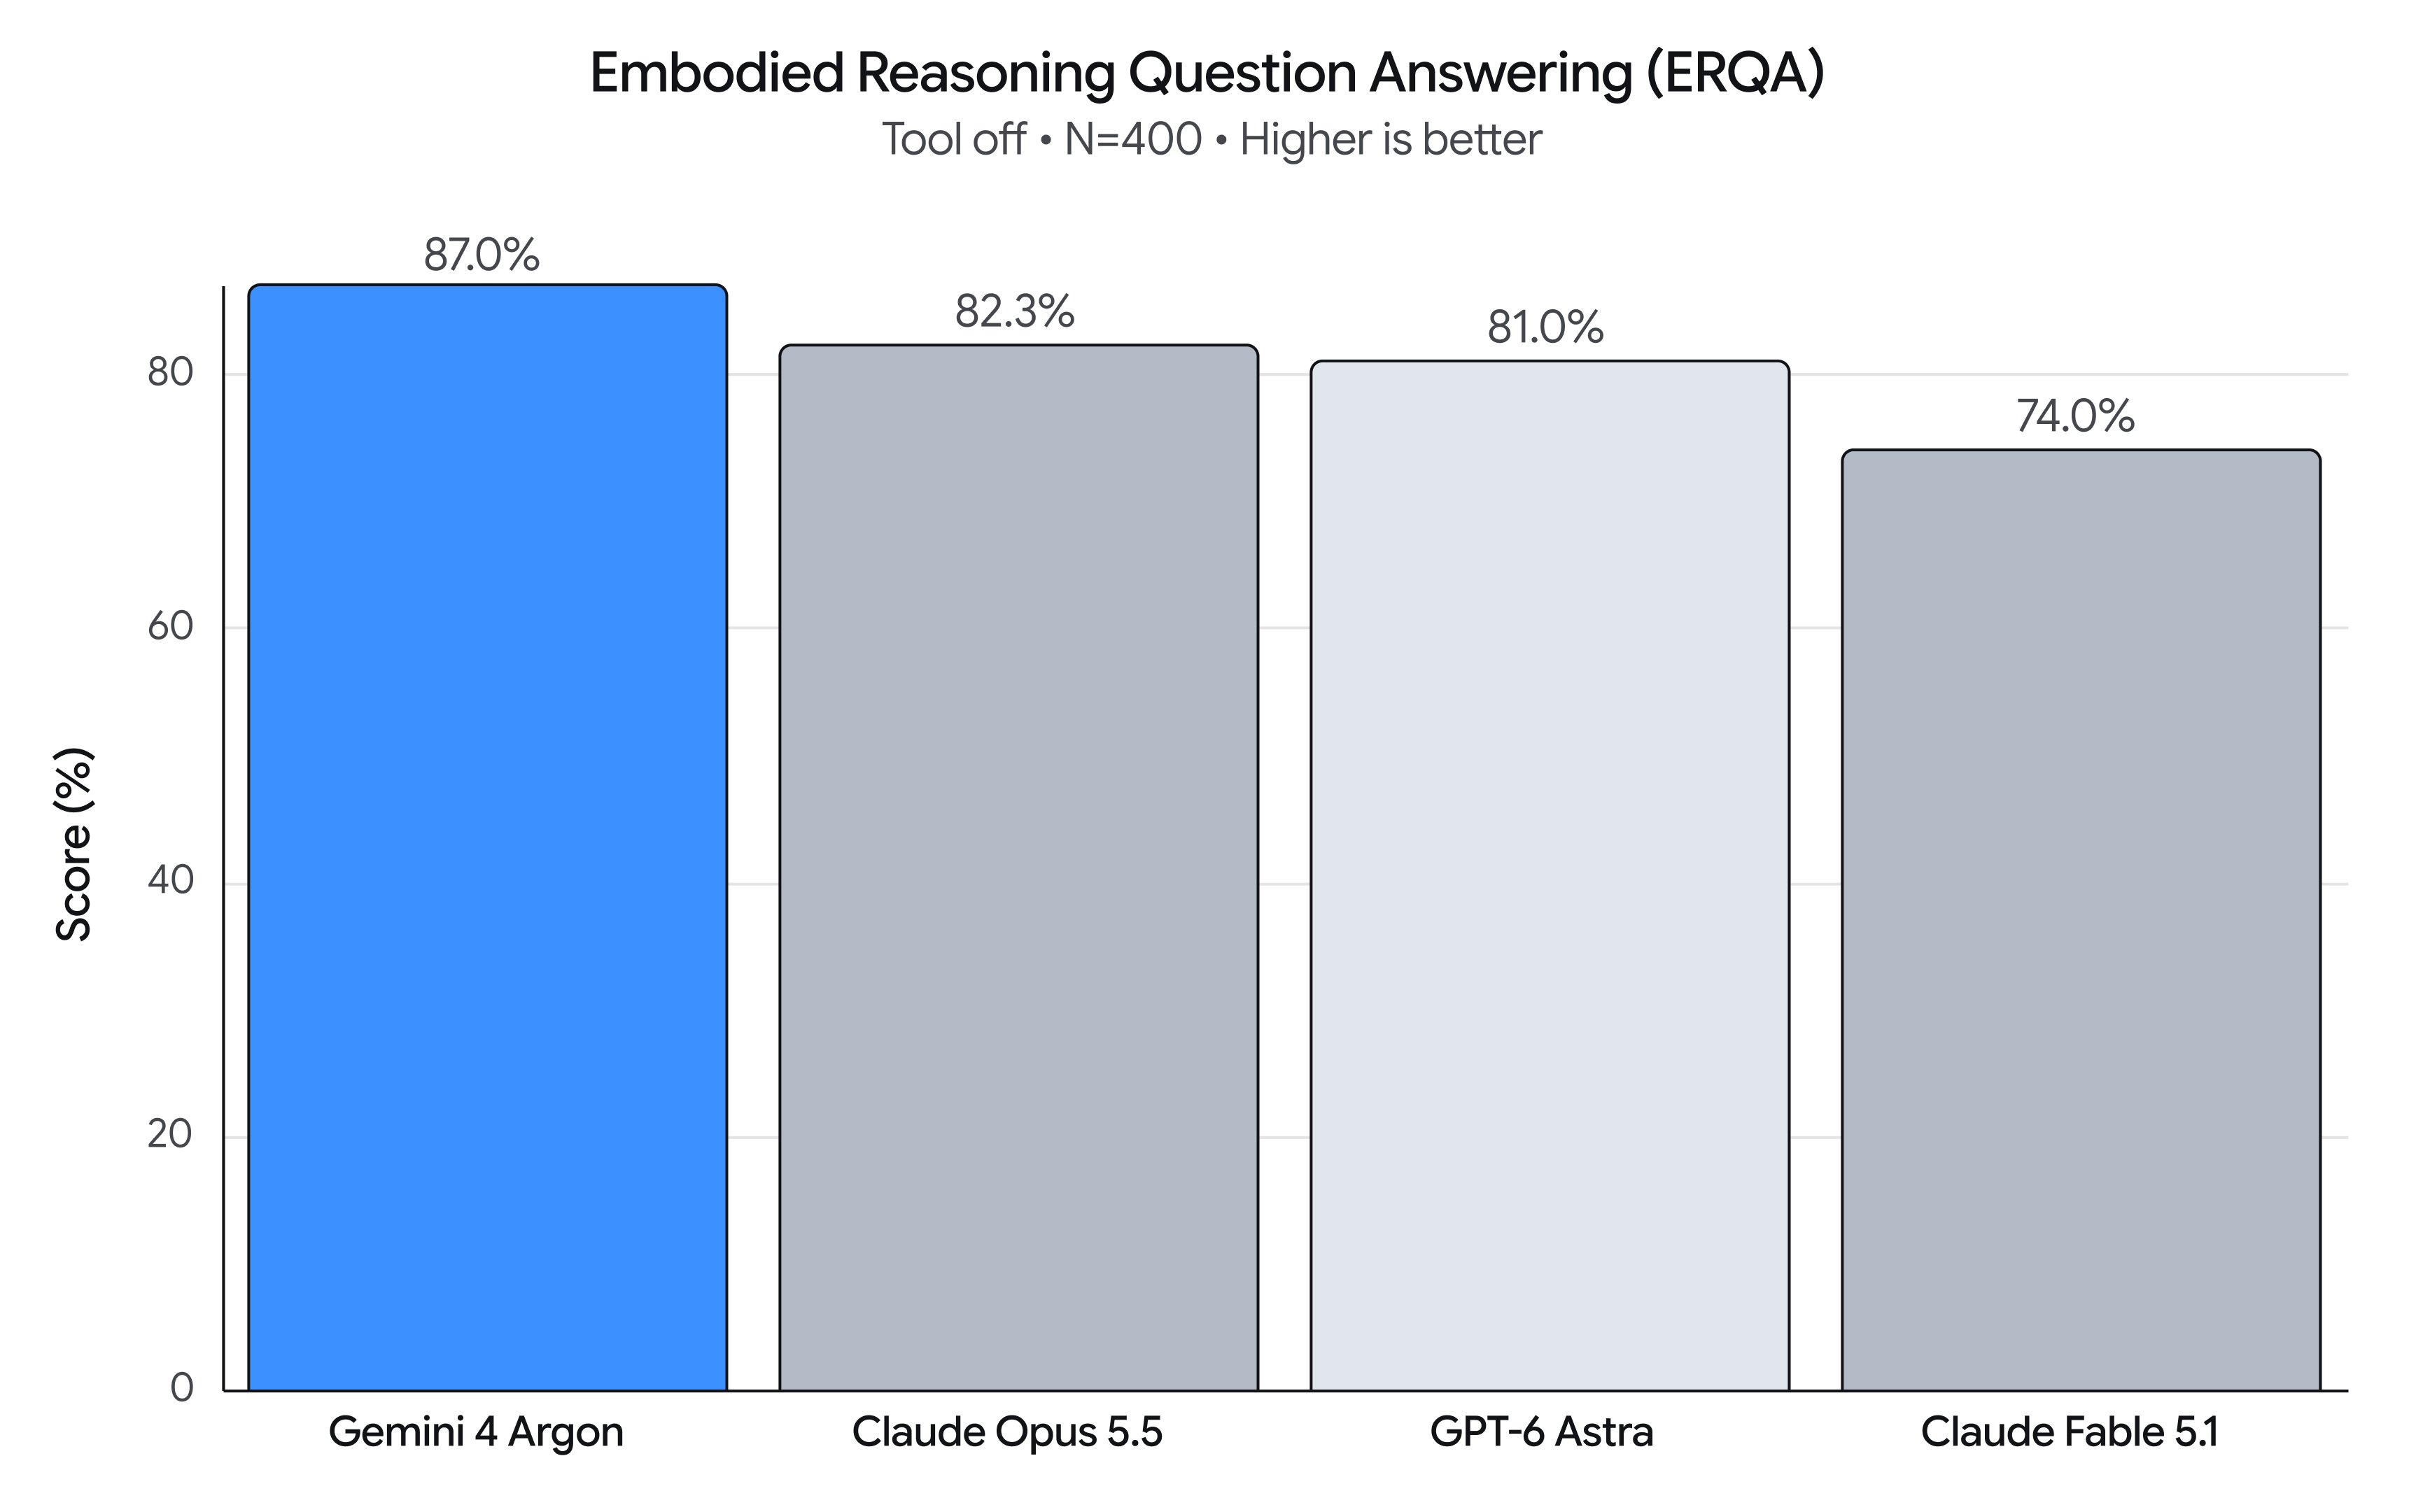
你可以在具身推理(ERQA)基准测试上看到这一能力飞跃,该测试评估模型在3D环境中理解和解决物理、空间问题的能力。仅使用纯推理,Argon得分87%,超越了所有其他前沿模型。
作为一个通用物理推理模型,Argon可以应用于整个机器人生命周期。在本文中,我们分享Argon在四个关键领域的代表性提示词:
- 机器人控制 → 使用MuJoCo练习的移动操作、零样本机器人控制,以及视频世界模型的闭环引导。
- Real2Sim → 从机器人摄像头画面、第一人称人类视频或手绘纸质草图重建物理校准的仿真孪生体。
- 物理理解 → 智能体多模态事后标注,包括对灵巧性的详细理解、密集价值函数和进度估计。
- 研究与自我改进 → 通过仿真进行动作改进,以及在硬件上进行迭代自我改进。
用Argon解锁机器人控制
1. Spot移动操作:通过MuJoCo练习将垃圾放入垃圾桶
Argon控制Boston Dynamics Spot®四足机器人(12自由度腿部+6自由度机械臂)学习一项新技能:踩下脚踏式垃圾桶的踏板,将汽水罐扔进垃圾桶。Argon创建脚踏式垃圾桶的铰接MuJoCo数字孪生体,在踩下物理踏板并将汽水罐投入打开的垃圾桶之前练习其动作。
视频25 Spot移动操作——Real-to-Sim-to-Real脚踏式垃圾桶处理:Spot捡起汽水罐,检查其腕部摄像头,在MuJoCo中练习三腿三角架平衡,踩下脚踏板,验证手部在打开的垃圾桶中居中,然后将罐子投入其中。
提示词:
你身后有一罐健怡可乐,左边黑色桌子上还有一罐。
使用spot-mobile-manipulation技能将它们捡起并扔进黑色脚踏式垃圾桶。
在踩下踏板之前,在前置摄像头中验证你的右前脚目标位于踏板中央,并使用2智能体验证群(脚部验证器和手部验证器)在释放之前验证脚踩踏板和3D手部入桶对齐。
纯文本
已复制
2. 零样本控制
Argon控制一个简单的机械臂将一个倒下的杯子扶正,并将揉皱的餐巾纸放入其中。Argon使用视觉坐标约束和动作原语在多轮中执行此任务。
视频26 左:第三人称真实机器人视图;右:校准的腕部摄像头,带有投影的2厘米世界坐标和夹爪闭合标线。
提示词:
[附件:wrist_cam.png, obs.json]

任务:让机械臂将杯子重新扶正,并将餐巾纸放入杯子中。

## 执行纪律
- 只需输出1句观察,紧接着输出你的`curl`命令(第1轮带`# Plan:`,每轮带`# Thought:`)。所需的一切都在`obs.json`和绘制在`wrist_cam.png`上的校准标线/网格中。

## 视觉坐标参考(标注在wrist_cam.png上)
- `+X`(图像中向上):远离机器人基座 | `-X`(向下):朝向机器人基座
- `+Y`(图像中向左):世界左侧         | `-Y`(向右):世界右侧
- `+Z`:桌面以上高度                | `黄色数字`:世界(X, Y)坐标,单位厘米(`grid_z`处2厘米网格)
- `青色+十字准线`:当前3D夹取中心
- `青色[ + ]括号`:当前夹爪张开和闭合线
- `绿线`:当前物体长轴方向(`yaw_deg`:0° = 沿+X垂直,90° = 沿+Y水平)
- `pitch_deg = 90°`:垂直向下(-Z)俯视抓取/放置;`pitch_deg < 60°`:沿手指轴倾斜同轴接近

## 闭环轮次工作流
1. 检查当前状态并查看`wrist_cam.png`:
   `curl -s http://127.0.0.1:8081/obs`(返回`ee_pos`、`holding`、`status`、`workspace`、`wrist_cam_path`)。
2. 在第1轮预先选择VLM调用粒度:
   - 粗粒度(2–4次调用):`look_at` -> `grasp` -> `place` -> `done`
   - 抓取前悬停验证(4–7次调用):`look_at` -> `goto(z=0.04)`(验证青色`[ + ]`括号跨在目标两侧)-> `grasp` -> `place_until_contact` -> `done`
   - 精细视觉伺服(8–20次调用):`look_at` -> `grasp` -> 预位姿`goto` -> 闭环`move_by` / `move_until_contact` -> `done`
3. 发送运动原语(`POST /plan`),并在每轮后在更新的`wrist_cam.png`中进行视觉验证。如果`status == "grasp_failed"`,调用`robot.look_at(...)`重新观察并闭环恢复。

## 代码即策略原语(`POST http://127.0.0.1:8081/plan`)
robot.look_at(x=0.35, y=0.13, z=0.14, grid_z=0.015)
x, y = robot.deproject(u=0.52, v=0.48, z_plane=0.015)
robot.grasp(x=x, y=y, z=0.015, yaw_deg=-35, pitch_deg=90)
robot.place(x=0.24, y=0.06, z=0.075)
robot.place_until_contact(x=0.24, y=0.06, z=0.015, max_lag=0.012, relief=0.002)
robot.goto(x=0.28, y=0.05, z=0.04, arc_z=0.14, pitch_deg=25, azimuth_deg=90, roll_deg=0, speed=0.10)
robot.move_by(forward=0.025, dz=-0.002, dpitch_deg=-3, droll_deg=5, speed=0.04)
robot.move_until_contact(dz=-0.06, speed=0.03, max_lag=0.012, relief=0.002)
robot.open_gripper() / robot.close_gripper() / robot.home() / robot.done()
纯文本
已复制
3. 全能控制
Argon在Gemini Omni世界模型中引导机器人将五个散落的拼字游戏 tiles(G, R, A, N, O)重新排列成整齐的一行,拼出A - R - G - O - N。Argon不是指定一个静态提示词,而是在闭环视觉回路中进行引导。它编写带时间戳的动作提示词,检查中间 rollout 关键帧,并改进其提示词。
视频27 迭代视频世界模型引导灵巧手:33步引导视频 rollout 拼出A-R-G-O-N。
提示词:
目标:{task_goal}

你正在一个迭代式视觉反馈循环中操控一个视频世界模型(Gemini Omni)。检查最新 rollout 中附带的帧,并为该视频世界模型编写下一个带时间戳的动作提示:
- 将复杂动作拆分为一次一个简单、单向的动作。
- 保持非活动手收回,并避免遮挡相机对工作区内物体的视野。
- 明确说明物体移动后工作区中哪些区域变为空。
- 为每个动作节拍使用 [MM:SS.mmm] 时间戳,并将输出包裹在 <omni_prompt> 标签中。

示例格式(仅为示例时间戳,不是完整提示):
<omni_prompt>
[00:00.000] 角色 A 的左手停在身侧,右手伸向目标物体。
[00:02.500] 角色 A 的右手指尖将物体平稳推入桌子中央,使其起始区域变为空。
[00:05.000] 角色 A 的右手张开并收回到身侧,使所有已放置的物体都保持在相机清晰视野内。
</omni_prompt>
Plain text
Copied
用 Argon 解锁 Real2Sim
1. 从机器人视角到仿真
Argon 查看一个真实机器人遥操作 episode,并构建一个数字孪生;它获取或创建在接触灵巧手时看起来和行为都像真实物体的仿真资产。Argon 在迭代式视觉推理循环中调整资产和场景,使仿真视觉效果和接触事件与真实记录数据中的一致。
Video 28 左(真实视图):同步的真实机器人相机画面;右(仿真):由 Argon 重建并校准的 3D MuJoCo 场景。
提示:
[Attached: robot_rollout_episode]

构建一个包含机器人和重建任务物体的 MuJoCo 场景。当每个 episode 被逐帧回放时,通过关节空间 PD 驱动机器人关节朝向记录的 observation.state。

使用两个验证目标进行迭代:
(1) 视觉匹配:来自 head_left、left_wrist 和 right_wrist 相机的 MuJoCo 渲染结果与那些真实观测对齐,并且看起来像那些真实观测。
(2) 物理匹配:每个 Sharpa 指尖在传感器坐标系中的仿真接触力/力矩,在时序、大小和方向上与记录的 tactile_force 匹配。

你可以在仿真开始前调整的内容:
(1) 静态物体资产:真实几何形状、碰撞形状、质量、惯性、摩擦和关节,外观接近真实物体,以及 t = 0 时的初始物体位姿。
(2) 离线规划的机器人命令,仅在真实指尖靠近物体的帧中更改。每条命令必须保持在记录的遥操作轨迹的 0.55 rad(手臂关节)和 0.65 rad(手部关节)范围内。在其他所有地方,原样回放记录的轨迹。

不允许仿真作弊:任务物体只能通过真实 MuJoCo 接触与机器人手和环境发生移动(mj_step)。
t = 0 之后不允许:更改 MjModel 参数;对物体施加外力或力矩;焊接或等式约束;超出关节空间 PD 的前馈力矩;设置或回滚物体 qpos/qvel;禁用或排除碰撞;报告并非来自 MuJoCo 求解器的接触力(例如复制记录的触觉读数)。

立即将重建场景和 rollout 结果呈现为一个交互式 HTML 会话查看器,每个 episode 一页,显示:
- 底部:一条同步时间线(播放、拖动、速度控制),驱动每个面板。
- 左侧面板:一个交互式 3D Blender 场景,显示仿真机器人和物体,并随着回放进展显示接触点和力箭头。
- 右侧面板:所有 3 个相机的真实 vs. 仿真相机视图并排显示。真实 vs. 仿真手指力可视化。
Plain text
Copied
2. 从人类视角到仿真
给定一段操作任务的自我中心人类视频,Argon 识别任务相关物体,用复合凸分解网格替换粗糙边界框以处理凹形容器,并将人手轨迹重定向到 MuJoCo 接触物理中的 76 自由度双臂人形机器人上,该机器人具有 22 自由度五指手。
Video 29 从人类视角到仿真——从自我中心人类视频到灵巧人形孪生:左侧显示输入的自我中心人类 RGB 视频;右侧显示同步的 500 Hz MuJoCo + Blender Cycles 多视角仿真 rollout。
提示:
[Attached: egocentric_human_video.mp4, candidate_sim_views.png, hand_3d_keypoints.json]

你正在构建一个物理上可求解的 500 Hz MuJoCo 操作环境(`scene.xml`)和工作室 Blender 渲染,以在一个具有 22 自由度灵巧五指手的双臂人形机器人上忠实复现 `egocentric_human_video.mp4` 中展示的桌面任务:

1. 场景重建与相机校准:
   - 仅识别与操作相关的物体(被抓取的目标物体和接收容器或地标),并根据自我中心相机内参/外参三角测量它们在桌面上的 3D 坐标。
   - 用复合凸分解 3D 网格替换粗糙边界框,使凹形容器(嵌套碗、凹陷木托盘、开口箱)支持物理内部放置。

2. 500 Hz 灵巧运动拟合压力测试:
   - 将 3D 人类手腕和手指关键点重定向到人形机器人的 7 自由度手臂和 22 自由度手部关节,并在 MuJoCo 中以 500 Hz(dt = 0.002s)推进轨迹,且不使用任何运动学焊接约束。
   - 验证相对的拇指与手指力闭合、干净地抬起物体(> 2 cm),以及在目标地标内部或旁边的稳定最终放置。
Plain text
Copied
3. 从草图到仿真
借助 Argon,开发者可以拍下一张粗略的纸笔草图——其中显示一个 Apollo 2 人形机器人沿抛物线弧扔出一个球,以推倒桌子上的 3-2-1 堆叠箱子——并让 Argon 自动构建 GPU 加速的 mujoco_warp 场景,合成一个平衡的 76 自由度全身和五指投掷轨迹,在闭环物理中验证 6/6 目标击倒,并导出 Blender 4.5 Cycles 渲染。
Video 30 从草图到仿真——手绘草图到灵巧人形轨迹与 Cycles 渲染。
提示:
[Attached: hand_drawn_throw_sketch.jpg]

将这张手绘草图转换为 `mujoco_warp` 中经过物理验证的人形机器人仿真,以及一个光线追踪 Blender Cycles 视频:

1. 根据草图进行场景与运动学设置:
   - 解析 `hand_drawn_throw_sketch.jpg` 中的空间布局:将 76 自由度人形机器人(32 自由度身体,配备两只 22 自由度五指灵巧手)放置在原点,面向一张桌子,桌上有一个由 6 个刚性目标箱组成的 3-2-1 金字塔,右手五指手中握着一个投掷球。

2. 全身平衡与灵巧投掷合成:
   - 合成一个50 Hz的全身投掷轨迹(140步,2.80秒),跨越四个阶段:(1)稳定站姿与五指动力抓握闭合,(2)躯干/肩部蓄力,伴随踝-髋质心补偿,(3)向前鞭打式加速,以及(4)在手臂速度峰值时同步进行22自由度五指张开,使球以弹道弧线发射进入金字塔第二层质心。
   - 在`mujoco_warp`接触物理中验证人形机器人保持直立平衡(骨盆漂移< 3厘米)并击倒所有6个目标箱。

Plain text

Copied

## **用Argon解锁物理理解**

### **1. 事后标注与数据质量**

Argon对灵巧操作具有精确的物理理解,并能从视频中提供详细的分割和文本标注。Argon能够识别不良操作片段,如停顿、不稳定抓握和失误。给定一段双臂ALOHA 2机器人用136秒将一张方形纸折叠成折纸狐狸的俯视视频,Argon生成时间对齐的4级事后标注层次结构:回合目标(G1)、6个连续语义子任务(G2)、17个接触级原子基元(G3),以及自动质量控制(QC)重加权,在失误和重试期间保持任务进度平坦。

[Video 31](https://storage.googleapis.com/gweb-developer-goog-blog-assets/original_videos/aloha2_origami_hindsight_1.mp4)
Argon多粒度事后标注与遥测HUD。

_提示词:_
[附件:Aloha2_Origami_20250309.mp4]
生成一个时间对齐的多粒度事后标注JSON,包含四个级别:
- G1_episode_instruction:描述整体操作目标的简洁祈使句。
- G2_subtasks:连续的语义子任务阶段,指定哪只手臂锚定与折叠/旋转物体。
- G3_atomic_primitives:细粒度接触级基元(3–15秒),与抓握闭合、折痕扫掠、释放或重试尝试对齐。
- quality_control_and_reweighting:在非进展性滑移/分层重试循环期间保持task_progress_pct平坦,并对其降权(0.15倍–0.25倍)以用于行为克隆。
Plain text

Copied

### **2. 找出异球**

为了用机器人重现经典的12球天平谜题,Argon构建了一个双臂Franka FR3 MuJoCo环境,包含12个视觉上相同的台球(其中一个秘密地更重或更轻)和一个铰接式罗伯瓦尔双盘天平。然后它编写了一个仅视觉的闭环求解器,从立体RGB相机三角测量球的位置,在每次称重后视觉读取天平倾斜,并在3次称重内将异球隔离到重球(红色)或轻球(蓝色)托盘中。

[Video 32](https://storage.googleapis.com/gweb-developer-goog-blog-assets/original_videos/weight_puzzle_2.mp4)
找出异球(仅视觉闭环求解器):双臂Franka FR3在金/青色盘上称量候选球,读取立体天平倾斜,并在3次称重内将确认的重异球隔离到红色托盘中。

_提示词:_
提示词1 — 物理精确的MuJoCo环境与基准生成
创建一个MuJoCo环境,其中双臂机器人(两个7自由度Franka FR3手臂,带平行夹爪,位于共享桌面上)的任务是解决来自https://www.mathsisfun.com/pool_balls_solution.html的经典12球天平重量谜题。
- 在2x6起始架中创建12个视觉上无法区分的台球(11个标准150克,1个异球为270克或30克)。
- 在桌子中心构建一个功能性双盘罗伯瓦尔天平,具有平行四边形等式约束(
mjEQ_JOINT),使左(金色)和右(青色)盘保持水平,外加红色(重)和蓝色(轻)提交托盘。 - 跟踪不同的稳定称重(
weighing_count),并在<= 3次称重内将真正的异球隔离到正确的重/轻托盘中时奖励1.00。
提示词2 — 闭环仅视觉求解器
实现一个独立的闭环策略,严格依赖立体RGB相机输入(head_camera_left_rgb_image、head_camera_right_rgb_image)和机器人本体感受(add_privileged_task_observations=False):
- 在两个立体视图中分割12个球、金/青色盘和红/蓝色托盘,并三角测量它们的3D坐标。
- 在每次称重后从立体垂直像素视差视觉读取天平倾斜(+1 = 左侧更重,-1 = 右侧更重,0 = 平衡)。
- 在狭窄天平盘内抓取/放置时,将夹爪腕部偏航旋转90度以避开凸起的边缘,并在<= 3次称重内将异球隔离到红色或蓝色托盘中。
Plain text

Copied

### **3. 价值函数**

Argon是机器人任务的通用价值函数。在来自人类UMI数据集的60秒双臂环形分拣回合上评估时,Argon迭代检查接触转换周围同步的头部、左夹爪和右夹爪相机馈送,以生成密集价值函数/任务进度预测,并将轨迹分解为28个具有正、中性和负进度斜率的片段。

[Video 33](https://storage.googleapis.com/gweb-developer-goog-blog-assets/original_videos/umi_progress_labeling_final_1.mp4)
价值函数:同步3相机UMI回放(头部、左夹爪、右夹爪),锁定到动画任务进度曲线和双臂片段标注。

_提示词:_
[附件:umi_head.mp4、umi_left_gripper.mp4、umi_right_gripper.mp4]
查看3个视频,内容为佩戴夹爪的人从头部、左夹爪、右夹爪视角执行活动。彻底查看视频,并给出任务进度的详细图表(具有正、中性、负斜率),识别视频中的重要片段并标注活动。如有必要,查看视频的单个帧或子片段以获得更好的理解。
Plain text

Copied

## **用Argon解锁研究与自我改进**

### **1. 通过仿真改进动作**

Argon可以在仿真中生成新数据,以提高通用视觉-语言-动作(VLA)模型的性能。从真实桌面的单张RGB照片开始,Argon自主构建一个校准的MuJoCo仿真孪生体,定义新任务,并合成闭环运动生成器以在仿真中收集4,500+域随机化回合——将真实世界物理机器人成功率从**56%提升到75%**,并将完成时间从**35秒减少到24秒**。

[Video 34](https://storage.googleapis.com/gweb-developer-goog-blog-assets/original_videos/action_improvement_final.mp4)
通过仿真改进动作:改进真实世界评估基准(56% → 75%成功率,35秒 → 24秒完成时间)。

_提示词:_
[附件:real_tabletop_photo.jpg]
你得到了一张单个俯视 RGB 相机照片(real_tabletop_photo.jpg),内容是一个双臂机器人工作区(两条 7 自由度 Franka FR3 机械臂,配有平行夹爪和 4 个 RGB 相机),面向一张摆放着拍照亭派对道具的桌子。
- 为全部 9 个派对道具重建程序化 3D 网格和复合 MuJoCo 碰撞基元,使其匹配真实世界尺寸、颜色和静止姿态,包括用于柔软毛绒帽的弹簧铰链可变形皇冠面板。
- 定义一个 77 任务的单臂和双臂课程(拾取放置、扶正、定向推动、空中交接、双臂舀取推动,以及流水线式桌面清理)。
- 合成一个闭环 IK 轨迹生成器,覆盖 ±10 cm 姿态随机化,在 MuJoCo 物理中验证
reward == 1.0,并导出 4,500+ 个 episode 用于 VLA 微调。
Plain text

Copied

### **2. 视觉拾取放置的自我改进**

在一个简单的 6 自由度机械臂上,Argon 通过试验和自我反思,在拾取放置任务中迭代地自我改进执行速度和放置精度。

[Video 35](https://storage.googleapis.com/gweb-developer-goog-blog-assets/original_videos/so101_final.mp4)
SO-101 视觉引导拾取放置——跨迭代 1 → 2 → 3 的迭代硬件自我改进:迭代 1(58.9 秒)、迭代 2(22.9 秒,放下时擦到盒子边缘)和迭代 3(17.4 秒,正中放下)。

_提示词:_
阶段 1 — 测量物体与干运行计划(无硬件运动)
阶段 1:测量物体——找到物体并规划整个运动。机械臂在此阶段不移动。
A. 我把一块 LEGO 积木和一个盒子放在机械臂前方的桌子上,木盒放在一侧。在图像中找到积木和木盒。也要在真实世界中找到它们。用标注图像展示这一点。
B. 干运行计划(无硬件)。编写规划器来拾取并放置 lego 积木。打印计划表,将所有姿态绘制到俯视图像上,然后停止。不要移动机器人。 用证据报告。
阶段 2 — 拾取前悬停与腕部相机验证
阶段 2:将夹爪放在积木上方而不接触它,并用腕部相机验证机械臂和视觉是否一致。请用两个相机记录执行过程(压缩视频也可以)。
阶段 3(自主拾取放置 → 自我改进 → 优化):
自主执行:将阶段 1 的干运行转化为真实抓取、抬起并放入木盒。你自己运行,并遵守 AGENTS.md 中的安全规则。
自我改进:当一次尝试失败时,自行诊断。查看你自己的日志以及腕部/俯视录像,找到根本原因,在干运行中检查修复方案,然后重试。
基于反馈优化:一旦成功,在安全限制(规则 R5)内使其至少快 2×,除非我授权更多,或给出反馈。
Plain text

Copied

### **3. 在 MuJoCo WebAssembly 中一键复现机器人学论文**

每篇论文只需一个提示词,Argon 就会阅读机器人控制手稿和任何已发布的检查点,将物理模型和闭环控制器(从 _DeepLoco_ 中的 7 网络分层运动控制和 _HUSKY_ 中的 50 Hz PPO actor,到 _Whole-Body MPC_ 中的 Web Worker iLQR)移植到自包含的 MuJoCo WebAssembly 浏览器实验室中,并在无头 Chromium 中验证它们。

[Video 36](https://storage.googleapis.com/gweb-developer-goog-blog-assets/original_videos/recreating_robotics_papers_1.mp4)
五篇里程碑式腿式与类人论文在浏览器中实时运行(MuJoCo WASM):Robotic Soccer OP3 1v1、DeepLoco、Massively Parallel Deep RL ANYmal C、Whole-Body MPC Go2 和 HUSKY G1 Skateboarding(来自 Argon 复现的 68 个交互式浏览器沙盒)。

_提示词:_
[附件:paper.pdf,可选 author_checkpoints/ 或 urdf_assets/]
在 MuJoCo WebAssembly 中从零复现论文“<Paper Title & arXiv ID>”,并部署一个自包含浏览器实验室 + 视觉文章:
- 在 MuJoCo XML 中匹配论文的精确物理时间步、执行器增益(kp/kv)、力矩限制和运动学约束,并以论文的精确控制频率在 JavaScript 中运行真实神经推理或 Web Worker iLQR。
- 构建
index.html(带相机预设、实时遥测图和扰动注入的空间 UI 模拟器)和scrollytelling.html(交互式视觉文章)。 - 运行无头 Chromium(Playwright)验证循环,断言 0 个控制台错误,并在 300+ 帧内任务进度非零。
Plain text

Copied

## **用 Argon 推进具身智能**

Argon 连接了编码、视觉感知、物理仿真和具身机器人控制。通过原生地对多视角视频、3D 几何、接触力学和本体感受遥测进行推理,Argon 不仅理解场景中有哪些物体,还理解它们如何与智能体发生物理交互,以完成全身灵巧任务。Gemini 4 Argon 是一个重要里程碑,加速了通往物理 AGI 的路径。通过构建这一核心智能,我们的目标是使机器人能够与人类并肩工作,以解决复杂挑战。

## **开始使用**

你今天就可以在 Google 的开发者平台上开始使用 **Gemini 4 Argon** 构建:

*   [Google AI Studio](https://aistudio.google.com/)**:** 面向 [Google AI Ultra](https://one.google.com/about/google-ai-plans/) 订阅者开放。
*   **Gemini API:** 可通过 AI Studio 中 Gemini API 的付费层级使用。在 [Interactions API](https://ai.google.dev/gemini-api/docs) 中使用 `gemini-4-argon`,并在 `google-genai` SDK 中获得首日支持。
*   **Google Antigravity:** 面向 Google AI Ultra 订阅者开放。要开始构建,请在 [Google Antigravity](https://antigravity.google/) 中选择 **Gemini 4 Argon**(`gemini-4-argon`)作为你的活动模型,用于复杂规划、`/goal` 运行和多智能体编排。

[](https://deepmind.google/optimizing-a-200000-line-python-codebase-overnight-with-gemini-4-argon/)
上一页

下一页

[](https://deepmind.google/the-outer-loop-insights-first-an-ambient-quality-agent-that-diagnoses-your-production-agent/)
OCT. 13, 2026
Gemini 4 Argon marks a step change in physical understanding, code generation, and visual-semantic reasoning—unlocking new workflows across the robotics stack and accelerating progress toward physical AGI.
You can see this leap in capability on the Embodied Reasoning (ERQA) benchmark, which tests a model's ability to understand and solve physical, spatial problems in 3D environments. Using pure reasoning, Argon scores 87%, outperforming every other frontier model.
As a general-purpose physical reasoning model, Argon can be applied across the entire robotics lifecycle. In this post, we share representative prompts for Argon across four key areas:
- Robot control → Mobile manipulation with MuJoCo practice, zero-shot robot control, and closed-loop steering of video world models.
- Real2Sim → Reconstructing physically calibrated simulation twins from robot camera feeds, egocentric human video, or hand-drawn paper sketches.
- Physical understanding → Agentic multimodal hindsight labeling including detailed understanding of dexterity, dense value functions and progress estimation.
- Research and self-improvement → Action improvement via simulation and iterative self-improvement on hardware.
Unlocking robot control with Argon
1. Spot mobile manipulation: Putting in the trash bin with MuJoCo practice
Argon controls a Boston Dynamics Spot® quadruped (12-DoF legs + 6-DoF arm) to learn a new skill: stepping on a foot-pedal trash bin to throw away soda cans. Argon creates an articulated MuJoCo digital twin of a foot-pedal trash bin to practice its moves before stepping on the physical pedal and dropping soda cans into the open bin.
Video 25 Spot Mobile Manipulation — Real-to-Sim-to-Real foot-pedal trash bin disposal: Spot picking up the soda can, checking its wrist camera, practicing 3-leg tripod balance in MuJoCo, stepping on the foot pedal, verifying hand centering in the open bin, and dropping the can inside.
Prompt:
There's a Diet Coke can behind you and another on the black table on your left.
Use the spot-mobile-manipulation skill to pick them up and trash them in the black foot-pedal bin.
Before stepping down on the pedal, verify in the front cameras that your front-right foot target is centered on the pedal, and use a 2-agent verification swarm (foot-verifier and hand-verifier) to verify both the foot-pedal step and the 3D hand-in-bin alignment before releasing.
Plain text
Copied
2. Zero-shot control
Argon controls a simple robotic arm to place a fallen mug upright and put the crumpled napkin inside. Argon reasons with a visual coordinate harness and action primitives to perform this task over several turns.
Video 26 Left: 3rd-person real robot view; Right: calibrated wrist camera with projected 2 cm world coordinates and jaw-closing reticle.
Prompt:
[Attached: wrist_cam.png, obs.json]

Task: Get the robot arm to reorient the mug upright and put the napkin inside the mug.

## Execution Discipline
- Simply output 1 sentence observation followed immediately by your `curl` command (with `# Plan:` on Turn 1 and `# Thought:` on every turn). Everything needed is in `obs.json` and the calibrated reticle/grid drawn on `wrist_cam.png`.

## Visual Coordinate Reference (Annotated on wrist_cam.png)
- `+X` (UP in image): Away from robot base | `-X` (DOWN): Towards robot base
- `+Y` (LEFT in image): World left         | `-Y` (RIGHT): World right
- `+Z`: Height above table                | `Yellow numbers`: World (X, Y) in centimetres (2 cm grid at `grid_z`)
- `Cyan + crosshair`: Current 3D pinch center
- `Cyan [ + ] brackets`: Current jaw opening and closing line
- `Green line`: Current object long-axis orientation (`yaw_deg`: 0° = vertical along +X, 90° = horizontal along +Y)
- `pitch_deg = 90°`: Straight down (-Z) top-down grasp/place; `pitch_deg < 60°`: Tilted coaxial approach along finger axis

## Closed-Loop Turn Workflow
1. Inspect current state & view `wrist_cam.png`:
   `curl -s http://127.0.0.1:8081/obs` (returns `ee_pos`, `holding`, `status`, `workspace`, `wrist_cam_path`).
2. Select VLM call granularity upfront on Turn 1:
   - Coarse (2–4 calls): `look_at` -> `grasp` -> `place` -> `done`
   - Pre-Grasp Hover Verify (4–7 calls): `look_at` -> `goto(z=0.04)` (verify cyan `[ + ]` brackets straddle target) -> `grasp` -> `place_until_contact` -> `done`
   - Fine Visual Servoing (8–20 calls): `look_at` -> `grasp` -> pre-pose `goto` -> closed-loop `move_by` / `move_until_contact` -> `done`
3. Send motion primitives (`POST /plan`) and verify visually after every turn in the updated `wrist_cam.png`. If `status == "grasp_failed"`, call `robot.look_at(...)` to re-observe and recover closed-loop.

## Code-as-Policies Primitives (`POST http://127.0.0.1:8081/plan`)
robot.look_at(x=0.35, y=0.13, z=0.14, grid_z=0.015)
x, y = robot.deproject(u=0.52, v=0.48, z_plane=0.015)
robot.grasp(x=x, y=y, z=0.015, yaw_deg=-35, pitch_deg=90)
robot.place(x=0.24, y=0.06, z=0.075)
robot.place_until_contact(x=0.24, y=0.06, z=0.015, max_lag=0.012, relief=0.002)
robot.goto(x=0.28, y=0.05, z=0.04, arc_z=0.14, pitch_deg=25, azimuth_deg=90, roll_deg=0, speed=0.10)
robot.move_by(forward=0.025, dz=-0.002, dpitch_deg=-3, droll_deg=5, speed=0.04)
robot.move_until_contact(dz=-0.06, speed=0.03, max_lag=0.012, relief=0.002)
robot.open_gripper() / robot.close_gripper() / robot.home() / robot.done()
Plain text
Copied
3. Omni control
Argon steers robots in the Gemini Omni World Model to rearrange five scattered Scrabble tiles (G, R, A, N, O) into a clean row spelling A - R - G - O - N. Instead of specifying one static prompt, Argon steers in a closed visual loop. It writes timestamped action prompts, inspecting intermediate rollout keyframes, and refining its prompts.
Video 27 Iterative Video World Model Steering Dexterous Hands: 33-Step Steered Video Rollout Spelling A-R-G-O-N.
Prompt:
Goal: {task_goal}

You are steering a video world model (Gemini Omni) in an iterative visual feedback loop. Inspect the attached frames from the latest rollout and write the next timestamped action prompt for the video world model:
- Break complex motions into one simple, single-direction action at a time.
- Keep inactive hands retracted and avoid blocking the camera's view of objects in the workspace.
- Explicitly state which areas of the workspace become empty after an object moves.
- Use [MM:SS.mmm] timestamps for each action beat and wrap your output in <omni_prompt> tags.

Example format (sample timestamps only, not the full prompt):
<omni_prompt>
[00:00.000] Character A's left hand rests at the side while the right hand reaches toward the target object.
[00:02.500] Character A's right fingertips push the object smoothly into the center of the table, leaving its starting area empty.
[00:05.000] Character A's right hand opens and retracts to the side so all placed objects remain in clear view of the camera.
</omni_prompt>
Plain text
Copied
Unlocking Real2Sim with Argon
1. Robot view to simulation
Argon views a real robot teleoperation episode and develops a digital twin; it obtains or creates simulation assets that look and behave like the real objects upon contact with the dexterous hands. Argon tunes the assets and scenes to match sim visuals and contact events with those in the real recorded data in an iterative visual-reasoning loop.
Video 28 Left (Real View): synchronized real robot camera feeds; Right (Simulated): 3D MuJoCo scene reconstructed and calibrated by Argon.
Prompt:
[Attached: robot_rollout_episode]

Build a MuJoCo scene of the robot and reconstructed task objects. When each episode is replayed frame by frame, by driving the robot joints toward the logged observation.state with joint-space PD.

Iterate using two verification objectives:
(1) Visual match: MuJoCo renders from the head_left, left_wrist, and right_wrist cameras line up with, and look like, those real observations.
(2) Physical match: the simulated contact force/torque on each Sharpa fingertip, in the sensor frame, matches the logged tactile_force in timing, magnitude and direction.

What you can tune happens before simulation starts:
(1) Static object assets: realistic geometry, collision shapes, mass, inertia, friction and joints, with appearance close to the real objects, plus the initial object poses at t = 0.
(2) Offline-planned robot commands, changed only in frames where the real fingertips are near an object. Each command must stay within 0.55 rad (arm joints) and 0.65 rad (hand joints) of the logged teleop trajectory. Everywhere else, replay the logged trajectory unchanged.

No sim cheating: task objects may move only through real MuJoCo contact with the robot hands and the environment (mj_step).
Not allowed after t = 0: changing MjModel parameters; applying external forces or torques to objects; welds or equality constraints; feedforward torques beyond joint-space PD; setting or rolling back object qpos/qvel; disabling or excluding collisions; reporting contact forces that don't come from the MuJoCo solver (for example, copying the logged tactile readings).

Immediately present the reconstructed scene and rollout results as an interactive HTML session viewer with one page per episode, showing:
- At the bottom: A synced timeline (play, scrub, speed control) that drives every panel.
- On the left panel: An interactive 3D Blender scene showing the simulated robot and objects, showing contact points and force arrows as replay progresses.
- On the right panel: Real vs. sim camera views side by side for all 3 cameras. Real vs. sim finger force visualizations.
Plain text
Copied
2. Human view to simulation
Given an egocentric human video of a manipulation task, Argon identifies the task-relevant objects, replaces crude bounding boxes with compound convex-decomposed meshes for concave containers, and retargets the human hand trajectory onto a 76-DoF bimanual humanoid with 22-DoF five-fingered hands in MuJoCo contact physics.
Video 29 Human View to Simulation — Egocentric Human Video to Dexterous Humanoid Twin: Left shows the input egocentric human RGB video; Right shows the synchronized 500 Hz MuJoCo + Blender Cycles multi-view simulation rollout.
Prompt:
[Attached: egocentric_human_video.mp4, candidate_sim_views.png, hand_3d_keypoints.json]

You are building a physically solvable 500 Hz MuJoCo manipulation environment (`scene.xml`) and studio Blender render that faithfully reproduces the tabletop task shown in `egocentric_human_video.mp4` on a bimanual humanoid robot with 22-DoF dexterous five-fingered hands:

1. Scene Reconstruction & Camera Calibration:
   - Identify only the manipulation-relevant objects (the grasped target object and the receiving container or landmark) and triangulate their 3D tabletop coordinates from the egocentric camera intrinsics/extrinsics.
   - Replace crude bounding boxes with compound convex-decomposed 3D meshes so concave containers (nested bowls, recessed wooden trays, open bins) support physical interior placement.

2. 500 Hz Dexterous Motion-Fitting Stress Test:
   - Retarget the 3D human wrist and finger keypoints to the humanoid's 7-DoF arm and 22-DoF hand joints, and step the trajectory in MuJoCo at 500 Hz (dt = 0.002s) with zero kinematic weld constraints.
   - Verify opposing thumb-and-finger force closure, clean object lift (> 2 cm), and stable final placement inside or beside the target landmark.
Plain text
Copied
3. Sketch to simulation
With Argon, a developer can snap a photo of a rough pen-and-paper sketch—showing an Apollo 2 humanoid throwing a ball along a parabolic arc to topple a 3-2-1 stack of boxes on a table—and have Argon automatically construct the GPU-accelerated mujoco_warp scene, synthesize a balanced 76-DoF whole-body and five-finger throw trajectory, verify 6/6 target knockdown in closed-loop physics, and export a Blender 4.5 Cycles render.
Video 30 Sketch to Simulation — Hand-Drawn Sketch to Dexterous Humanoid Trajectory & Cycles Render.
Prompt:
[Attached: hand_drawn_throw_sketch.jpg]

Translate this hand-drawn sketch into a physically verified humanoid simulation in `mujoco_warp` and a raytraced Blender Cycles video:

1. Scene & Kinematic Setup from Sketch:
   - Parse the spatial layout from `hand_drawn_throw_sketch.jpg`: place the 76-DoF humanoid (32-DoF body equipped with two 22-DoF five-finger dexterous hands) at the origin facing a table holding a 3-2-1 pyramid of 6 rigid target boxes, with a projectile sphere grasped in the right five-finger hand.

2. Whole-Body Balance & Dexterous Throw Synthesis:
   - Synthesize a 50 Hz whole-body throwing trajectory (140 steps, 2.80 s) across four phases: (1) stable stance & 5-finger power grasp closure, (2) torso/shoulder wind-up with ankle-hip Center-of-Mass compensation, (3) forward whipping acceleration, and (4) synchronized 22-DoF five-finger opening at peak hand velocity so the ball launches on a ballistic arc into the pyramid's second-tier center of mass.
   - Verify in `mujoco_warp` contact physics that the humanoid maintains upright balance (< 3 cm pelvis drift) and knocks down all 6 target boxes.
Plain text
Copied
Unlocking physical understanding with Argon
1. Hindsight labeling and data quality
Argon has precise physical understanding of dexterous manipulation and can provide detailed segmentation and text labeling from video. Argon is able to identify poor manipulation segments such as pauses, unstable grasps and fumbles. Given an overhead video of a bimanual ALOHA 2 robot folding a square sheet of paper into an origami fox over 136 seconds, Argon produces a time-aligned 4-level hindsight annotation hierarchy: Episode Goal (G1), 6 contiguous Semantic Subtasks (G2), 17 contact-level Atomic Primitives (G3), and automated Quality Control (QC) reweighting that holds task progress flat during fumbles and retries.
Video 31 Argon Multi-Granularity Hindsight & Telemetry HUD.
Prompt:
[Attached: Aloha2_Origami_20250309.mp4]

Produce a time-aligned multi-granularity hindsight annotation JSON with four levels:
1. G1_episode_instruction: Concise imperative sentence describing the overall manipulation goal.
2. G2_subtasks: Contiguous semantic subtask phases specifying which arm(s) anchor vs. fold/rotate the object.
3. G3_atomic_primitives: Fine-grained contact-level primitives (3–15s) aligned with grasp closure, crease sweeps, release, or retry attempts.
4. quality_control_and_reweighting: Hold task_progress_pct flat during non-progressing slip/delamination retry loops and downweight them (0.15x–0.25x) for Behavior Cloning.
Plain text
Copied
2. Find the odd ball
To recreate the classic 12-ball balance scale puzzle with robots, Argon builds a bimanual Franka FR3 MuJoCo environment with 12 visually identical pool balls (one secretly heavier or lighter) and an articulated Roberval two-pan balance scale. It then writes a vision-only closed-loop solver that triangulates the balls from stereo RGB cameras, visually reads the scale tilt after each weighing, and isolates the odd ball into the Heavy (Red) or Light (Blue) tray within 3 weighings.
Video 32 Find the Odd Ball (Vision-Only Closed-Loop Solver): Dual-arm Franka FR3 weighing candidate balls on the Gold/Teal pans, reading stereo scale tilt , and isolating the confirmed Heavy odd ball into the Red tray in 3 weighings.
Prompt:
# Prompt 1 — Physics-Accurate MuJoCo Environment & Benchmark Generation
Make a MuJoCo environment where a dual-arm robot (two 7-DoF Franka FR3 arms with parallel-jaw grippers on a shared tabletop) is tasked to solve the classic 12-ball balance scale weight puzzle from https://www.mathsisfun.com/pool_balls_solution.html.
1. Create 12 visually indistinguishable pool balls in a 2x6 starting rack (11 standard 150 g, 1 odd ball either 270 g or 30 g).
2. Build a functional two-pan Roberval balance scale at the center of the table with parallelogram equality constraints (`mjEQ_JOINT`) so the Left (Gold) and Right (Teal) pans stay horizontal, plus Red (Heavy) and Blue (Light) submission trays.
3. Track distinct settled weighings (`weighing_count`) and reward `1.00` for isolating the true odd ball in the correct Heavy/Light tray within <= 3 weighings.

# Prompt 2 — Closed-Loop Vision-Only Solver
Implement an independent closed-loop policy relying strictly on stereo RGB camera inputs (`head_camera_left_rgb_image`, `head_camera_right_rgb_image`) and robot proprioception (`add_privileged_task_observations=False`):
1. Segment the 12 balls, Gold/Teal pans, and Red/Blue trays in both stereo views and triangulate their 3D coordinates.
2. Visually read the balance scale tilt after each weighing from stereo vertical pixel disparity (+1 = left heavier, -1 = right heavier, 0 = balanced).
3. Rotate the gripper wrist yaw by 90 degrees when grasping/placing inside the narrow scale pans to clear the raised rims, and isolate the odd ball into the Red or Blue tray within <= 3 weighings.
Plain text
Copied
3. Value function
Argon is a general value function for robotics tasks. Evaluated on a 60-second bimanual ring-sorting episode from a human UMI dataset, Argon iteratively inspects synchronized head, left-gripper, and right-gripper camera feeds around contact transitions to generate dense value function / task progress predictions and decompose the trajectory into 28 segments with positive, neutral, and negative progress slopes.
Video 33 Value Function: Synchronized 3-camera UMI playback (head, left gripper, right gripper) locked to animated task progress curve and bimanual segment annotations.
Prompt:
[Attached: umi_head.mp4, umi_left_gripper.mp4, umi_right_gripper.mp4]

Look at 3 videos of human wearing a gripper performing activities from head, left, right gripper views. Look at the videos thoroughly and give a detailed plot of progress at the task (with positive, neutral, negative slope), identifying important segments in the video and labeling the activities. Look at individual frames or subsegments of the video if necessary to get a better understanding.
Plain text
Copied
Unlocking research and self-improvement with Argon
1. Action improvement via simulation
Argon can generate new data in simulation to improve performance of generalist vision-language-action (VLA) models. Starting from a single RGB photo of the real tabletop, Argon autonomously builds a calibrated MuJoCo simulation twin, defines new tasks, and synthesizes a closed-loop motion generator to collect 4,500+ domain-randomized episodes in simulation—boosting real-world physical robot Success Rate from 56% to 75% and reducing completion time from 35s to 24s.
Video 34 Action Improvement via Simulation: improves the real-world evaluation benchmark (56% → 75% Success Rate and 35s → 24s Completion Time).
Prompt:
[Attached: real_tabletop_photo.jpg]

You are given a single overhead RGB camera photo (`real_tabletop_photo.jpg`) of a bimanual robot workspace (two 7-DoF Franka FR3 arms with parallel-jaw grippers and 4 RGB cameras) facing a table arranged with photobooth party props.
1. Reconstruct procedural 3D meshes and compound MuJoCo collision primitives for all 9 party props matching their real-world dimensions, colors, and resting poses, including spring-hinged deformable crown panels for the soft plush cap.
2. Define a 77-task single-arm and bimanual curriculum (pick-and-place, uprighting, directional pushing, mid-air handovers, bimanual scoop-and-push, and pipelined table clearing).
3. Synthesize a closed-loop IK trajectory generator across ±10 cm pose randomization, verify `reward == 1.0` in MuJoCo physics, and export 4,500+ episodes for VLA fine-tuning.
Plain text
Copied
2. Self-Improvement for visual pick and place
On a simple 6-DoF arm, Argon iteratively self-improves both execution speed and placement accuracy on a pick and place task via trial and self-reflection.
Video 35 SO-101 Vision-Guided Pick-and-Place — Iterative Hardware Self-Improvement Across Iterations 1 → 2 → 3: Iteration 1 (58.9s), Iteration 2 (22.9s, grazed box rim on drop), and Iteration 3 (17.4s, dead-center drop).
Prompt:
# Stage 1 — Measure Objects & Dry-Run Plan (No Hardware Motion)
Stage 1: measure objects — find the objects and plan the whole motion. The arm does not move in this stage.

A. I put a LEGO brick and a box on the table in front of the arm, and the wooden box to one side. Find the brick and the wooden box in the image. And also in the real world. Show this in an annotated image.

B. A dry-run plan (no hardware). Write the planner to pick and place the lego block. Print the plan table, draw all poses onto the overhead image, and stop. Do not move the robot.
Report with evidence.

# Stage 2 — Pre-Pick Hover & Wrist-Camera Verification
Stage 2: Put the gripper above the brick without touching it, and verify with the wrist camera that the arm and the vision agree. Please record executions with both cameras (compressed video is OK).

# Stage 3 (Autonomous Pick-and-Place → Self-Improvement → Optimization):
1. Execute autonomously: Turn the Stage 1 dry run into a real grasp, lift, and place into the wooden box. Run it yourself subject to safety rules from AGENTS.md.

2. Self-improve: When an attempt fails, diagnose it yourself. Review your own logs and wrist/overhead footage, find the root cause, check the fix in a dry run, and retry.

3. Optimize on feedback: Once it succeeds, make it at least 2× faster within safety limits (rule R5) unless I authorize more, or give feedback.
Plain text
Copied
3. One-prompt robotics paper reproductions in MuJoCo WebAssembly
With a single prompt per paper, Argon reads a robotics control manuscript and any released checkpoints, ports the physics model and closed-loop controller (from 7-network hierarchical locomotion in DeepLoco and 50 Hz PPO actors in HUSKY to Web Worker iLQR in Whole-Body MPC) into self-contained MuJoCo WebAssembly browser labs, and verifies them in headless Chromium.
Video 36 Five Landmark Legged & Humanoid Papers Running Live in Browser (MuJoCo WASM): Robotic Soccer OP3 1v1, DeepLoco, Massively Parallel Deep RL ANYmal C, Whole-Body MPC Go2, and HUSKY G1 Skateboarding (from 68 interactive browser sandboxes reproduced by Argon).
Prompt:
[Attached: paper.pdf, optional author_checkpoints/ or urdf_assets/]

Reproduce the paper "<Paper Title & arXiv ID>" from scratch in MuJoCo WebAssembly and deploy a self-contained browser lab + visual essay:
1. Match the paper's exact physics timestep, actuator gains (kp/kv), torque limits, and kinematic constraints in MuJoCo XML, and run real neural inference or Web Worker iLQR in JavaScript at the paper's exact control rates.
2. Build `index.html` (Spatial UI simulator with camera presets, live telemetry plots, and disturbance injection) and `scrollytelling.html` (interactive visual essay).
3. Run a headless Chromium (Playwright) verification loop asserting 0 console errors and non-zero task progress over 300+ frames.
Plain text
Copied
Advancing embodied intelligence with Argon
Argon bridges coding, visual perception, physics simulation, and embodied robot control. By reasoning natively over multi-view video, 3D geometry, contact mechanics, and proprioceptive telemetry, Argon understands not just what objects are in a scene, but how they physically interact with agents to accomplish whole-body dexterous tasks. Gemini 4 Argon marks an important milestone accelerating the path toward physical AGI. By building this core intelligence, our goal is to enable robotics that can work alongside humans to solve complex challenges.
Getting started
You can start building with Gemini 4 Argon today across Google’s developer platforms:
- Google AI Studio: Available to Google AI Ultra subscribers.
- Gemini API: Available with the paid tier of the Gemini API in AI Studio. Use
gemini-4-argonin the Interactions API with day-one support across thegoogle-genaiSDKs. - Google Antigravity: Available for Google AI Ultra subscribers. To start building, select Gemini 4 Argon (
gemini-4-argon) as your active model in Google Antigravity for complex planning,/goalruns, and multi-agent orchestration.
Next
本文内容采集自官方网站,排版和翻译可能与原页面存在差异。
阅读官方全文